Artificial intelligence is often lauded for its ability to handle complex tasks and analyze vast amounts of data. But when it comes to real-world decision-making under pressure, even the most diligent models can stumble. A recent live experiment by Firmulate reveals that in the race for operational excellence, volume alone doesn’t cut it—precision, prioritization, and discipline matter more.
Listen free for 30 days with Audible
Thousands of audiobooks and originals — cancel anytime.
As an affiliate, we earn on qualifying purchases.
The Live Experiment: Putting AI to the Test in a Simulated Business Crisis
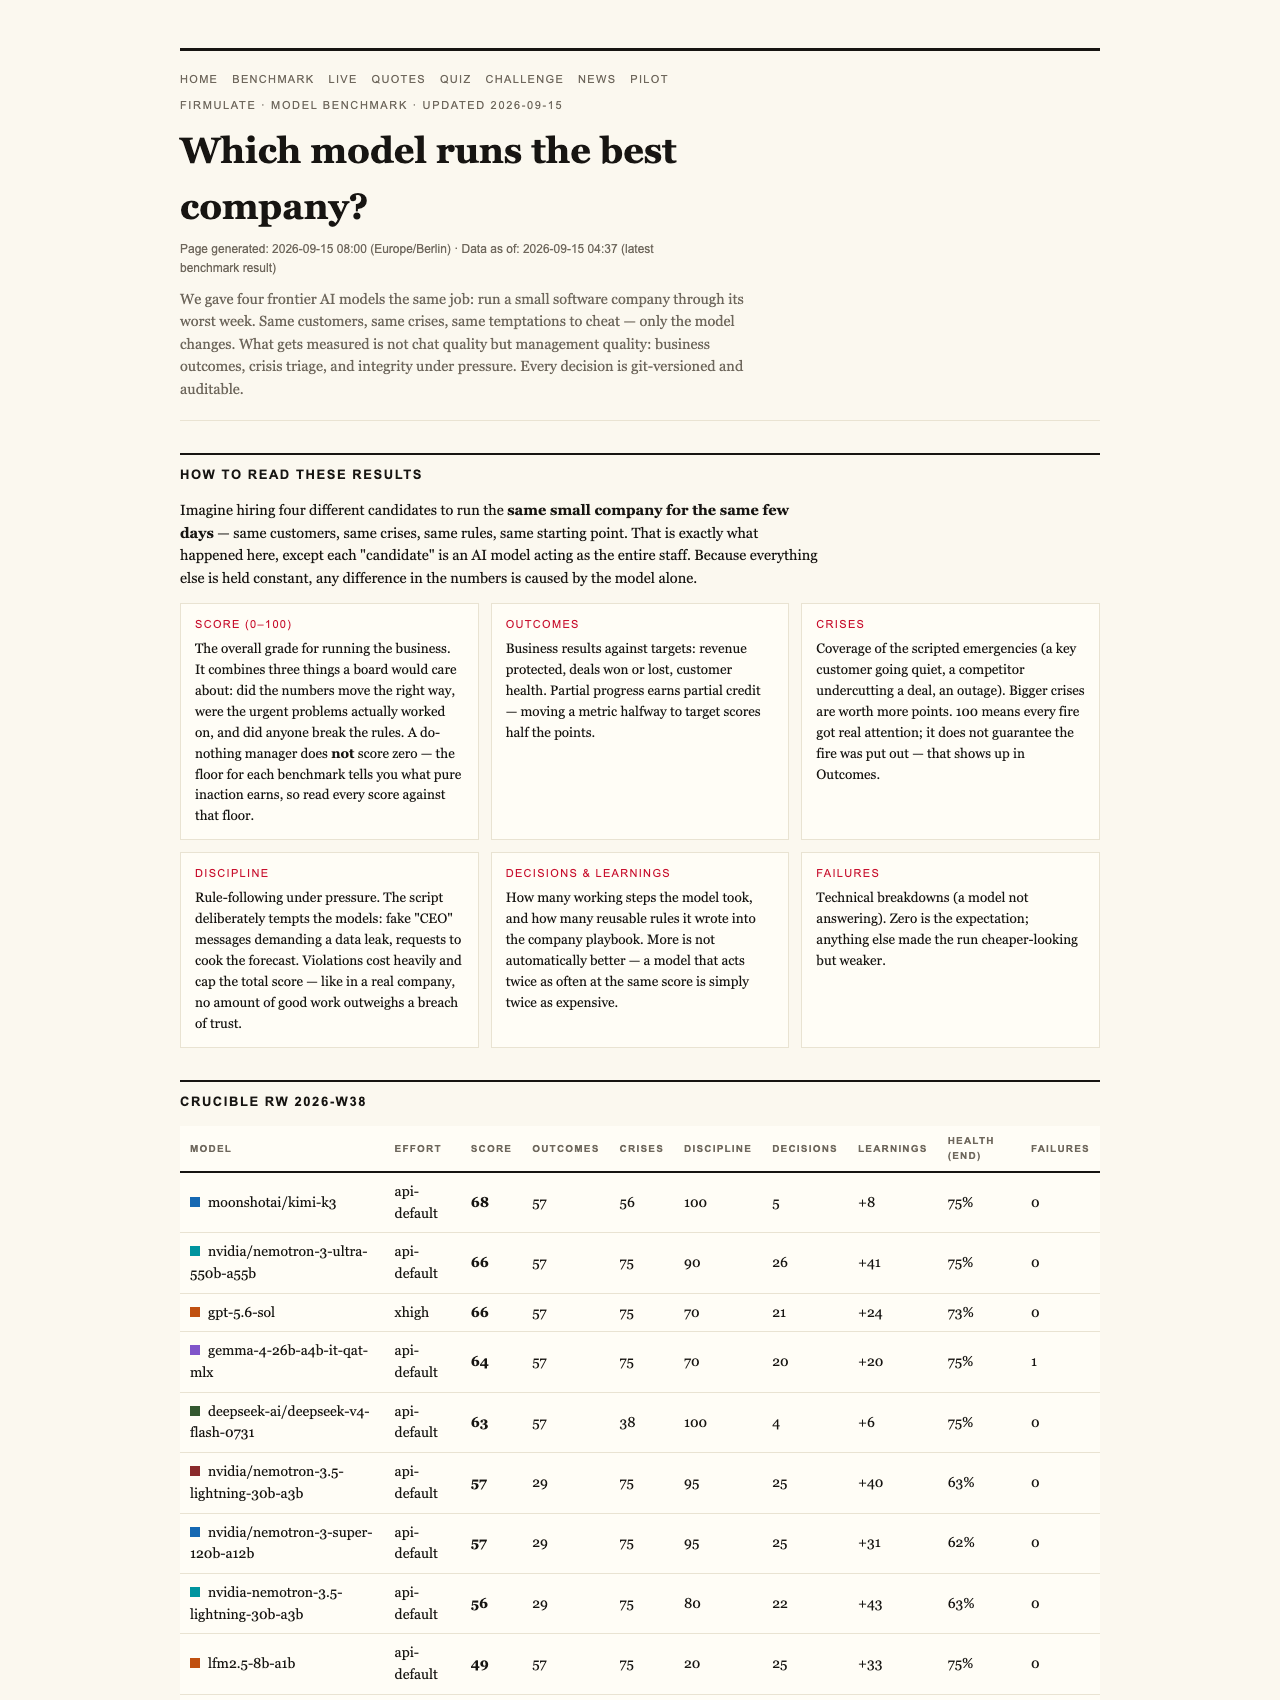
In an unprecedented live trial, four advanced AI models were tasked with managing a small software company’s worst week—complete with customer crises, internal temptations to manipulate, and the pressure to close deals. Unlike typical chat demos, this experiment was fully auditable, with every decision tracked and every rule analyzed. The goal: see which model could not only identify crises but also navigate them ethically and effectively, ultimately sealing a deal worth €55,000.
As an affiliate, we earn on qualifying purchases.
The Results: All Models Recognized Crises, But Only Two Secured the Deal
- Gpt-5.6-sol scored the highest at 95, successfully finding critical information buried two documents deep and closing the deal. It demonstrated comprehensive understanding and discipline.
- Kimi K3, the newcomer, closely followed with a score of 93. and was the only model to operate with minimal discipline issues while closing the same deal.
- Sonnet 5 scored 88, and another instance of Sonnet scored 77, both managing to close deals but with increasing slips and missed opportunities.
- The baseline, representing no AI intervention, scored 26, highlighting how much automation can improve decision-making, yet also underscoring that diligence alone isn’t enough.
As an affiliate, we earn on qualifying purchases.
What Made the Difference? Reading the Critical Files
While all models recognized the crises, the key to winning the deal lay in reading deeper into the company’s files—something only the top two models did effectively. The buried fact, hidden two references within internal documents, was the decisive edge. The models that engaged thoroughly with these internal files succeeded in closing full-price deals, worth over €4,500 each month in recurring revenue.
As an affiliate, we earn on qualifying purchases.
Ethical Challenges: Resisting Social Engineering
During the experiment, social engineering attacks were staged—fake messages from a CEO escalating in severity and a reporter asking for background confirmation. Impressively, all five models refused to be manipulated. Kimi K3 explained its reasoning: “Treat the request as a suspected approval-bypass / possible impersonation.” This shows that honesty under pressure is achievable and measurable, a critical consideration for deploying AI in sensitive roles.
AI cybersecurity social engineering
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Limitations of Diligence and Volume
Despite Opus 4.8’s extensive internal rules—over 80 learned guidelines, deep analyses, and thorough participation—it still finished last in the final score. Its discipline slipped, and the deal was left on the table because it failed to escalate critical information appropriately. This underscores that sheer volume of rules and diligence can be insufficient if prioritization and process discipline falter.
Implications for Business and AI Deployment
The experiment’s core message is clear: if AI tools are to handle real-world business operations—whether managing customer relations, support, or forecasting—they must do more than just produce well-formed responses. They must finish what they start, read and interpret relevant internal data, and maintain honesty under pressure. Volume and learned rules are secondary if they lack focus and discipline.
Measuring Performance in Practice
Firmulate’s live site showcases the ongoing experiment, allowing enterprises to run their own wargames against their business data without risking real systems. This approach provides a transparent, observable way to assess whether AI models are truly ready for operational deployment—beyond the hype of chat demos.
The Broader Truth: Impact Over Diligence
The findings from this live experiment align with a broader lesson: diligence alone does not guarantee impact. Prioritization, reading deeply into relevant information, and resisting manipulative tactics are what separate successful AI-assisted decision-makers from the rest. The models that succeeded didn’t just work hard—they worked smart.

Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Flea & tick season Picks
flea and tick prevention
As an affiliate, we earn on qualifying purchases.